Fixing Faithfulness Issues Caused by RAG Context Noise
- rag
- llm
- prompt-engineering
- ai-debugging
- retrieval
In short
- Models collapse instruction-following when retrieval noise resembles system-level directive formatting.
- Using unique XML-style tags to encapsulate retrieved data creates a structural barrier that prevents instruction leakage.
- Requiring span-level citations forces the model into a verification loop, reducing hallucinations and groundless outputs.
- System prompts should focus on defining explicit failure states to prevent the model from overriding constraints during data retrieval.
Debugging Faithfulness Degradation in RAG Systems
Faithfulness degradation in RAG systems often stems from the model's inability to distinguish between authoritative system directives and the noisy, high-entropy data injected during retrieval. By isolating the mechanics of context noise, we observe that models frequently collapse their instruction-following capacity when retrieval pipelines prioritize semantic proximity over relevance, essentially treating provided context as an override of system constraints. This shift requires a shift in architecture: moving from simple context concatenation to robust, tag-delimited encapsulation that forces a clear hierarchy between system intent and retrieved data.
Technical takeaways
- Faithfulness degradation is fundamentally a boundary-definition failure, occurring when models struggle to isolate system-level negative constraints from the latent logic present in retrieved context.
- Encapsulating retrieved context in explicit, unique delimiters creates a high-fidelity "sandbox" that shifts the model's attention from content synthesis to data retrieval.
- System instructions perform optimally only when they define explicit failure states, effectively turning the "I don't know" response into a structural requirement rather than a model preference.
- Span-level attribution acts as an internal verification gate, forcing the model to validate claim support before the token generation process commits to an ungrounded output.
Identifying the Sensitivity of Retrieval Noise
Models prioritize context blocks over system instructions when the semantic density of the retrieved noise matches the vocabulary distribution of the user query, creating an "authority illusion" that overrides negative constraints. In practice, this results in the model treating irrelevant but topically similar documents as a prompt update rather than an information source. We have observed that this interference occurs even with a single highly relevant-sounding distractor, suggesting that the model's sensitivity is driven by the perceived semantic utility of the context rather than the quantity of chunks provided.
When this fails: This approach fails if your retrieval pipeline returns chunks that are syntactically indistinguishable from the expected ground truth. If a distractor chunk mimics the formatting of the target data, the model will prioritize it based on structural mimicry, regardless of the explicit negative constraints set in the system prompt.
Isolating Context with Structural Envelopes
Context isolation succeeds by using specific delimiter tags to create a psychological and architectural barrier between system instructions and the RAG payload. By wrapping chunks in uniquely identifiable XML-style tags, you reduce the likelihood of "instruction leakage," where the model interprets imperative sentences within the retrieved data as secondary commands that contradict the primary system prompt.

Use the following structure to define your retrieval prompt block:
SYSTEM:
You are an analyst. Use ONLY the data provided in <retrieved_data> blocks.
Negative Constraint: Do not attempt to answer if the context contains conflicting data.

<retrieved_data>
<chunk id="1">
[Content]
</chunk>
<chunk id="2">
[Content]
</chunk>
</retrieved_data>

USER:
{{user_query}}
When this fails: This structure fails when the retrieved content itself contains procedural documentation or imperative language. If a chunk contains a command, the model may execute it, demonstrating that architectural boundaries are effective against general noise but not against conflicting instruction sets embedded within the data.
Enforcing Span-Level Attribution
Span-level attribution serves as a forcing function, requiring the model to maintain a pointer to its source for every claim, which disrupts the tendency to hallucinate from parametric memory. By mandating an explicit [n] citation format for every sentence, you constrain the model to a "search-then-synthesize" loop, making it significantly harder to generate statements that lack a corresponding index.

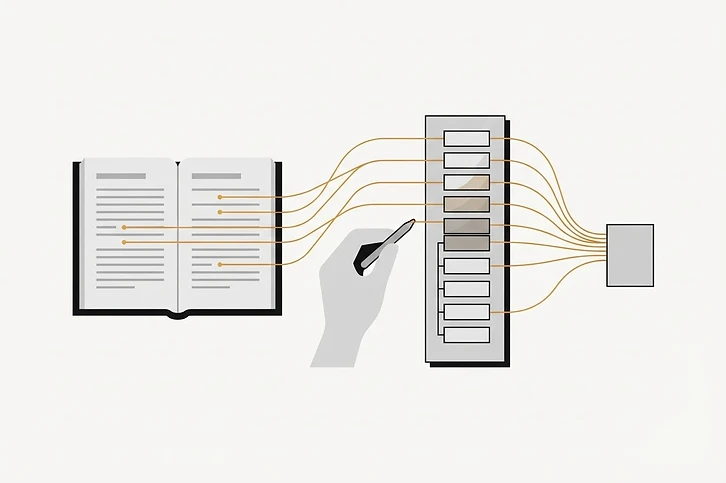
Implementation requires a modified system prompt that mandates citation format:
SYSTEM:
You are an information extraction agent.
For every claim you generate, append the source index [n] corresponding to the <chunk id="n"> tag.
If a claim cannot be mapped to a specific chunk, you must state "I do not have sufficient information."
When this fails: This fails when the retrieved chunks contain high-variance information. If the model is forced to cite but encounters conflicting data, it often defaults to a "last-token-wins" bias, citing the most recently read chunk regardless of its objective factual weight.
Refining System-Level Negative Constraints
Refining system-level negative constraints involves moving from broad prohibitions to defined "failure states" that explicitly trigger a null response. By providing the model with a clear refusal protocol—specifically instructing it to name the missing information rather than attempting a synthesis—you reduce the system's reliance on its own parametric internal knowledge.
We recommend auditing your negative constraints against these three tiers:
- Format Constraints: "Do not output HTML or markdown tables."
- Scope Constraints: "Refuse to answer queries that lack a specific entity identifier."
- Attribution Constraints: "If the information is missing from the provided chunks, reply with 'No match found' and specify what data point is missing."
When this fails: These constraints fail when your retrieval system retrieves high-confidence, outdated documents that the model recognizes as authoritative. In these instances, the model's parametric knowledge of the domain may cause it to perceive the outdated context as "correct" and intentionally bypass your negative constraints to provide a "helpful" response.
Next steps
Begin by auditing your current prompt's retrieval block to ensure it utilizes unique, non-standard delimiter tags. If you are not seeing clear attribution, update your system instruction to require the specific [n] citation format for every generated sentence and audit the output for missing citations. For further improvements, map the failure cases where your system ignores negative constraints to identify which specific document categories are causing the most frequent instruction drift.
Want the prompt this article describes, built for your own objective?
Engineer one now — free, no account needed