Improve Data Extraction Accuracy With Field Level Validation
- llm
- data-extraction
- evals
- json
- engineering
In short
- Monolithic LLM judges suffer from evaluation conflation, where aggregate confidence scores mask specific field errors.
- Decoupling validation logic into per-field schemas improves audit transparency and failure identification.
- Per-field trust scoring allows for custom precision requirements tailored to the business impact of specific data points.
- Field-level validation is less effective for checking complex logical dependencies between multiple fields.
Field-Level Trust Scoring Versus Monolithic Judge Evaluation
Monolithic judge evaluation fails because LLMs distribute responses across an entire JSON payload, often masking errors in nested fields behind scores for simpler top-level keys. By decoupling validation into per-field trust scoring, we isolate failure modes and prevent precision dilution in complex extraction pipelines. This approach specifically addresses the question: Field-Level Trust Scoring Versus Monolithic Judge Evaluation in Extraction Pipelines — Why monolithic single-call LLM judges suffer from evaluation conflation when assessing complex JSON payloads, and how per-field validation splits recover audit precision across high-density extraction workflows.
Technical takeaways
- Monolithic prompts suffer from evaluation conflation, where the judge balances the assessment of the entire payload at the expense of specific field accuracy.
- Schema-aware validators restrict the critique scope to specific data contracts rather than holistic semantic assessment.
- Evaluation debugging paths are improved by isolating assessment logic, providing transparency absent in single-call assessment methods.
The Failure of Monolithic Extraction Evaluation
Monolithic evaluation prompts ask an LLM to assess an entire JSON object for correctness in a single pass. This approach triggers evaluation conflation, where the model must simultaneously balance the correctness of structural integrity, data type adherence, and semantic accuracy. When one field is accurate but another is incorrect, the model’s aggregate evaluation often prioritizes the high-confidence components, leading to an aggregate score that obscures granular failures.
When we observe this, a system that extracts metadata from a multi-field invoice might report a high confidence score despite a specific field, such as a tax_id, containing errors. The judge treats the large volume of boilerplate text as a signal that dominates the smaller, incorrect extraction.
Implementing Per-Field Trust Scoring
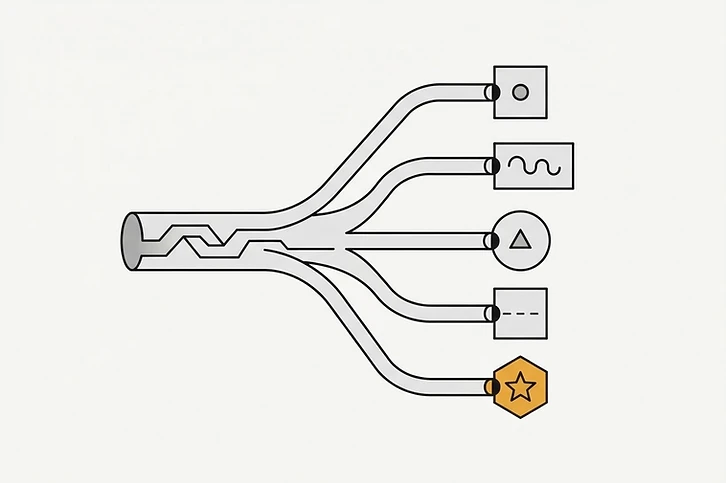
We replace the single prompt with a registry of field-specific validators that execute to ensure precision. Instead of asking "Is this JSON correct?", we define a contract for each field and query the model specifically against that schema definition to isolate failure modes.

# Example of per-field validation orchestration
def validate_payload(data):
    results = {}
    validators = {
        "invoice_id": validate_regex(r"INV-\d{4}"),
        "total_amount": validate_range(0, 100000),
        "currency": validate_in_list(["USD", "EUR", "GBP"])
    }

    for field, validator in validators.items():
        results[field] = validator.check(data.get(field))

    return results
By decoupling these, we prevent the "masking effect" where errors in low-density fields are lost in the total output. If a field is missing, the validator returns a specific error rather than a generic flag for the document.
Precision Gains in High-Density Pipelines
Shifting to per-field validation allows developers to apply different precision requirements and custom validation logic to individual fields based on their business impact. A monolithic judge cannot distinguish between a fuzzy-matchable customer_name and a strictly-formatted transaction_hash, whereas a split architecture enables tailored instructions for each specific data point.

Bypassing structural conflation
Structural accuracy is often conflated with semantic accuracy in LLM judges, leading to inflated confidence scores for technically valid but factually incorrect JSON. By isolating fields, we separate structural checks—such as verifying JSON validity—from content checks that determine if the value is supported by the source document.
When this fails
Field-level validation is ineffective when fields possess strong cross-field dependencies, such as an is_taxable boolean field whose validity depends on the customer_country field. In these cases, per-field scoring can miss errors because the judge validates both fields as "accurate" in isolation, failing to detect that the logical relationship between them is broken.
Strategic Abandonment of Holistic Critique
We move away from batch evaluation because it does not solve the underlying conflation that plagues monolithic extraction pipelines. When the LLM is forced to evaluate an entire object, it may generate a narrative justification for errors rather than identifying the specific constraint violation required for high-density extraction workflows.
The validator registry pattern
The validator registry pattern treats the extraction pipeline as a unit-tested system. When a model fails to extract a field correctly, the specific validator provides a clear audit log of which constraint failed, converting an opaque "model failure" into a transparent "schema violation," which is easier to fix in the system prompt on our platform.
Next step
Map your current monolithic judge prompts to your JSON schema, identifying the fields that suffer most from incorrect outputs, and replace their portion of the evaluation with a dedicated regex or type-check validator.
Want the prompt this article describes, built for your own objective?
Engineer one now — free, no account needed