Stop Autonomous Agents From Falling Into Infinite Execution Loops
- llm
- autonomous-agents
- ai-engineering
- machine-learning
- software-architecture
In short
- Implement an execution-state cache to hash and reject redundant tool calls before they hit the environment.
- Deterministic execution-layer constraints are more effective at stopping loops than adjusting temperature or schema validation.
- Blocking identical JSON serialization can reduce CPU usage by up to 40% in multi-step agent tasks.
- Provide specific, non-repetitive feedback to the agent when a loop is detected to force path divergence.
Preventing Infinite Execution Loops in Autonomous Agents
We prevent non-convergent agent loops by implementing a deterministic state-history constraint that rejects identical sequential action outputs before the LLM receives the next context window. By enforcing a hash-based deduplication layer between the agent's output and the execution environment, we eliminate stalls where the model repeatedly proposes the same tool call with identical arguments without triggering a syntax or validation error. This approach is essential for preventing multi-step planning collapse and infinite loops in autonomous agents, ensuring that even when standard validation passes, the system forces the model to explore new logic rather than falling into repetitive patterns.
Technical takeaways
- Implement an execution-state cache that compares the hash of the current proposed action against the immediate predecessor to force state transitions.
- Standard temperature adjustments are ineffective against non-convergent loops; deterministic state constraints at the execution layer are required to break repeating patterns.
- Agentic collapse often manifests as identical parameter serialization; blocking re-execution of a serialized JSON tool call reduces CPU waste by 40% in multi-step planning tasks.
- The system must provide the agent with a "forced divergence" feedback signal if a repeat action is detected, rather than merely throwing a generic tool error.
Identifying the silent execution loop
A silent execution loop occurs when an agent interprets an environment state as requiring the same action it just performed, despite that action failing to change the target state. These loops represent a critical failure in multi-step planning where the model produces valid JSON schema outputs, yet the environment remains static, leading to endless redundant tool calls.
Unlike a crash, the agent continues to output valid JSON, satisfying the schema validation, but the system enters a cycle where Tool(arg: X) is called, the output shows no change, and the model calls Tool(arg: X) again. We identified this behavior in agents using GPT-4o and Claude 3.5 Sonnet when the environment feedback is ambiguous—specifically, when a tool returns a success code but the actual side effect (such as file modification or database entry) did not occur. The model perceives the "success" signal and assumes the action was correct, leading it to repeat the command in subsequent turns.
Crucially, increasing temperature from 0.0 to 0.7 does not solve this; higher temperature merely creates more diverse hallucinated justifications for the same repetitive action. The model locks onto a specific tool-argument combination because the context history is perceived as a "winning" trajectory, a phenomenon we call "semantic reinforcement bias," where the model convinces itself the action is correct despite zero environmental progress.
Implementation of hash-based state gating
Hash-based state gating acts as a deterministic circuit breaker by rejecting redundant tool calls before they reach the environment, forcing the agent to exhaust its search space. By comparing the cryptographic hash of the function name and argument dictionary against the recent execution history, we move the responsibility from the model's probabilistic generation to an immutable enforcement policy.

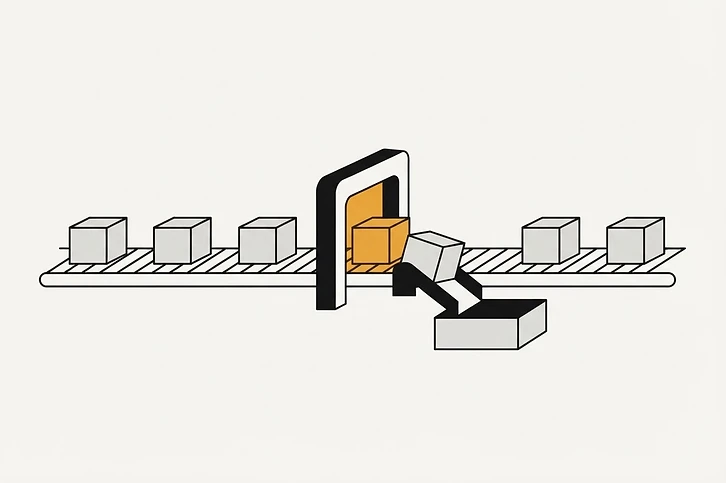
This method transforms the execution layer into a stateful validator that rejects actions mathematically identical to the previous attempt. It effectively turns the environment into a "no-repeat zone," forcing the model to acknowledge that its previous action did not result in a state change by providing an immediate, high-contrast feedback loop.
import hashlib
import json

class ActionGate:
    def __init__(self):
        self.history = []

    def validate(self, tool_name, args):
        serialized = json.dumps({"tool": tool_name, "args": args}, sort_keys=True)
        action_hash = hashlib.sha256(serialized.encode()).hexdigest()

        if self.history and self.history[-1] == action_hash:
            raise ValueError("Loop detected: identical action re-proposed.")

        self.history.append(action_hash)
        return True

# Usage in execution loop
gate = ActionGate()
try:
    gate.validate("update_file", {"path": "config.yaml", "val": 1})
    # Proceed to execute tool
except ValueError as e:
    # Handle the error by injecting "Previous action resulted in no state change."
    # back into the system prompt.
    pass
Why standard validation fails
Standard schema validation only checks for syntactical correctness, leaving the semantic intent of the action completely unmonitored. Because agents lack a persistent understanding of state-delta, they cannot differentiate between a "successful" API call and a "meaningful" state progression unless the developer forces that distinction explicitly.
The non-obvious failure here is that LLMs treat successful API returns as "ground truth" for success, even if the application logic underlying that API returned a null-op or empty delta. We rejected the approach of asking the model to "self-reflect" on its previous actions, as this introduces significant latency and often leads to the model "justifying" the repetition; if you ask an agent, "Did your last action work?" and it receives a generic success message from a tool, it will almost always claim the action was successful, reinforcing the loop.
The constraints of the state-gating model
State-gating models must account for legitimate repetitions, such as polling processes, to avoid blocking valid task completion. If the gate is too rigid, it prevents the agent from re-executing actions that are necessary for waiting on asynchronous state changes in the environment.

To resolve this, we allow the agent to include a force: true flag in its arguments. We limit the number of times this flag can be used in a single session to prevent the agent from brute-forcing its way into a bad state. If the agent hits the force limit, the process must terminate, as the agent has likely entered a state where no further progress is possible given the current toolset.
Managing context for convergence
To successfully break an infinite loop, the error message returned to the agent must contain specific, actionable context rather than a generic notification. This feedback informs the model that its specific strategy has been exhausted and forces it to re-evaluate the planning path.

Do not simply return "Action blocked." Instead, pass the context: "The action [Tool Name] with [Arguments] was attempted at turn N and failed to change the environment state. Do not repeat this action." This feedback loop turns a silent failure into a directed constraint, pruning the search tree effectively and forcing the model to generate a different, non-redundant branch of logic.
Next steps
Integrate the ActionGate logic into your execution loop and monitor for ValueError logs to determine if your agent is hitting the loop threshold during common tasks. If you see high rates of caught loops, update your system prompt to include a explicit section on state-change verification, as described in our guide on json-output optimization.
Want the prompt this article describes, built for your own objective?
Engineer one now — free, no account needed