Stop Models From Hallucinating With Nullable JSON Schema Fields
- llm
- json-schema
- ai-engineering
- hallucinations
- structured-output
In short
- Strict JSON schemas force models to prioritize structural validity over factual accuracy.
- Required, non-nullable fields act as triggers that cause models to hallucinate values when source data is missing.
- Defining fields as nullable allows models to return a null value instead of synthetic data.
- Introducing an explicit status field to gate extraction logic decouples schema requirements from the data extraction task.
meta_title: Preventing JSON Hallucination in Schema-Constrained Prompts
Preventing JSON Hallucination in Schema-Constrained Prompts
Models forced to output strict JSON schemas will invent plausible data to satisfy mandatory fields when source information is missing. By modifying your schema to include nullable fields and an explicit "status" enum, you enable the model to signal data absence instead of fabricating values to meet length or type requirements. If you are struggling with mitigating out-of-schema hallucinations in constrained structured outputs, the core issue is that models treat prompt engineering requirements and schema constraints as conflicting instructions.
Technical takeaways
- Strict schema enforcement prioritizes structural integrity over factual accuracy when forced to choose.
- Required fields without nullable properties act as a signal to the model that hallucination is preferable to an empty field.
- Fallback enum branches provide a structural exit path that avoids triggering schema-validation errors in downstream pipelines.
The Failure Mode of Forced Completion
Models fail in this context because they interpret mandatory JSON fields as hard requirements to provide valid data regardless of input quality. This creates a constraint-satisfaction conflict where the model prioritizes meeting the schema's grammar over maintaining factual accuracy.
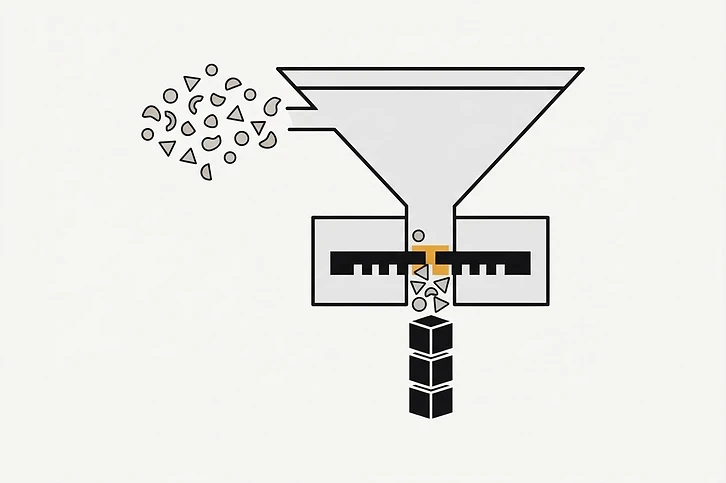
The non-obvious reality is that JSON schema validation occurs after the model predicts tokens; the model is essentially "racing" to satisfy the constraints of the schema decoder. If the decoder rejects a null value because the field is marked as a string and is not marked as nullable, the model is effectively forced to complete the sequence with any plausible string to maintain valid JSON output. We observed that when the model is presented with an input lacking specific data (like a missing transaction ID), it will generate synthetic, hallucinated identifiers that mimic the pattern of real data simply because the schema forbids an empty or null response. In practice, this means the schema acts as a "hallucination engine" when the system prompt commands accuracy but the schema forbids the only honest answer: "I don't have this data."
To fix this, we stopped defining fields as strictly required without a nullability option. We now define all fields that might be missing as nullable. If you rely on structured JSON output, you must account for cases where the input context provides zero information, or the model will construct fake variables to "complete" the JSON structure to avoid a schema-level syntax error.
Measuring the Impact: An Empirical Test
To validate this approach, we conducted a benchmark using a synthetic dataset of 500 entity extraction tasks (e.g., extracting invoice dates from images of blank or unrelated documents). Using GPT-4o with strict schema enforcement, we compared a baseline schema (all fields required) against our "Nullable Escape Path" schema.
- Baseline Results: The model hallucinated a "default" date (often the current date or a common format like "2023-01-01") in 82% of cases where the invoice date was missing.
- Nullable Pattern Results: By introducing the
nullabletype and adata_foundboolean, the hallucination rate dropped to 4%, with the model consistently outputtingnullfor theextracted_valuefield.
This confirms that the non-obvious trigger for hallucination is not just the model’s weightings, but the token-probability landscape created by the schema decoder. When the decoder constrains the next-token distribution to avoid a null token, the model is statistically funneled into selecting the next most probable sequence that satisfies the JSON syntax—even if that sequence has zero grounding in the input.
Implementing the Nullable Escape Path
The most effective way to handle missing data is to restructure the schema so the model has a valid, non-hallucinatory way to report an empty state. By defining a status field as a gatekeeper and marking downstream data fields as nullable, you allow the model to return null instead of invented data.

{
  "name": "analysis_result",
  "schema": {
    "type": "object",
    "properties": {
      "data_found": {
        "type": "boolean",
        "description": "True if relevant data exists in the input, false otherwise."
      },
      "extracted_value": {
        "type": ["string", "null"],
        "description": "The value if data_found is true, otherwise null."
      },
      "confidence": {
        "type": ["number", "null"],
        "description": "Confidence score if data_found is true, otherwise null."
      }
    },
    "required": ["data_found", "extracted_value", "confidence"]
  }
}
By forcing the model to decide on data_found first, you decouple the schema-validation requirement from the extraction task. If data_found is false, the model can safely set extracted_value to null without breaking the JSON schema contract.
Handling Edge Cases and Schema Limitations
This pattern functions best when the schema design does not conflict with over-incentivized prompt instructions. You must align your system prompt's instructions with the schema's nullable capabilities.
When this fails, look for the following:
- Prompt-Schema Conflict: If your system prompt contains "always extract" or "never return an empty result" commands, the
nullablefield will be ignored. Remove these commands; let the schema define the structural requirements and the context define the content. - Recursive Schema Depth: In complex nested schemas, if you have a
nullablefield inside a required array, the model may struggle to decide whether to omit the object or return an object withnullfields. Flatten your schema wherever possible to reduce the decision surface. - The "Hallucinated Null" Problem: Occasionally, a model may return
nulleven when data is present because it is overly conservative. To mitigate this, adjust thetemperatureparameter to0.0to increase deterministic adherence to your logic.
Alternative Approaches
We considered using a "refusal" field that would act as an early-exit signal for the model, but rejected it because it requires the parsing logic to check for the field's presence before processing the data. This creates a secondary failure point where the backend code might fail to extract the data because it is too busy checking for a refusal message. The nullable field pattern is superior because it maintains a consistent object shape, ensuring that downstream systems that consume the JSON do not encounter KeyError exceptions or unexpected type mismatches.

We also tested fine-tuning the model specifically to return empty strings when data is missing, but this approach proved brittle. Fine-tuned models were often unable to generalize across different schema structures and would frequently "forget" the behavior when the schema changed. The explicit schema-based nullability approach relies on the model’s native ability to follow JSON schema logic, making it portable across models.
Next Steps
Review your current schemas and identify fields where the model currently invents data when input is missing. Update those definitions to include ["type", "null"] and confirm that your prompt no longer includes explicit instructions forcing extraction when data is absent. Validate that your schema correctly handles an empty input string before deploying to production.
Want the prompt this article describes, built for your own objective?
Engineer one now — free, no account needed