Stop Overloading Your LLM Prompts with Multiple Instructions
- prompt engineering
- llm
- ai debugging
- data pipelines
- generative ai
In short
- Multi-objective prompts cause priority drift where models ignore formatting constraints in favor of generative flow.
- Serial sub-prompt staging uses a multi-step pipeline to isolate extraction from formatting.
- Decoupling tasks enables intermediate validation, allowing you to catch errors before the final output generation.
- Complex tasks should be ordered by volatility, moving creative generation to the start and rigid formatting to the end.
Debugging Overloaded Prompts by Decomposing Multi-Objective Instructions
Bundling multiple transformation instructions into a single prompt triggers selective constraint dropping, a behavior where the model prioritizes core semantic generation while discarding secondary formatting or stylistic constraints. This occurs because the model treats a list of instructions as a weighted set of priorities rather than a rigid, ordered pipeline. When a developer stacks a "summarize this text" directive with a "format as JSON" constraint and a "use professional, non-jargon tone" stylistic requirement, the model faces a conflict between the generative task and the structural constraints.
The solution is to decompose multi-objective instructions into deterministic sub-tasks using serial sub-prompt staging. By isolating each objective, you eliminate "constraint interference," where the latent representation of one goal (the structure of JSON) is polluted by the requirements of another (the creative tone of the prose).
The Engineering Reality: Why "Constraint Interference" Occurs
A competent engineer knows that LLMs operate via probability distribution over token sequences. In a monolithic, multi-objective prompt, the model must simultaneously fulfill competing goals. When the model is asked to be both creative and strictly structural, it does not "understand" the hierarchy of your prompt; it treats the combined instruction as a unified semantic space.
The non-obvious outcome of this overloading is priority drift. The model will favor the most semantically dense parts of the prompt—the generative task—because those tokens appear more frequently in the training distribution associated with the primary intent. Consequently, structural constraints (like JSON schemas) or negative constraints (like "do not use academic jargon") are treated as lower-priority signals and are dropped if they conflict with the generative flow.
Crucially, this failure is not random; it is structural. Because the model must maintain the coherence of the generated prose, any constraint that forces the model to move into a "lower probability" state—such as stopping a sentence to insert a JSON bracket or avoiding a word that is statistically probable in a given context—is often sacrificed to maintain the flow of the primary output.
When This Fails
You will see this phenomenon manifest in specific, repeatable patterns:
- Schema Collapse: The model begins the requested JSON structure but reverts to plain text to finish a complex explanation.
- Instruction Leakage: An earlier "persona" instruction persists into a later task where it is inappropriate.
- Ghost Constraints: The model includes a required header or footer but ignores the specific character count or indentation rules provided alongside it.
The Architecture of Serial Sub-Prompt Staging
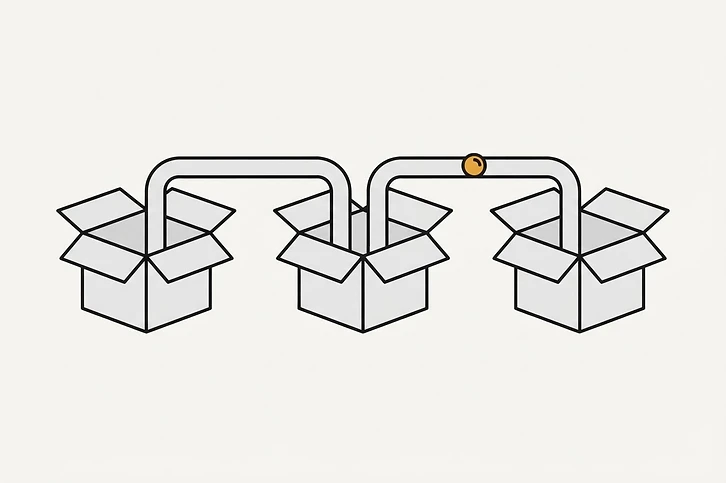
Serial staging restores deterministic execution by refactoring complex objectives into a sequence where each step performs one verifiable transformation. By treating prompt execution as a pipeline, where the output of Task A becomes the sole input for Task B, you ensure the model has no competing instructions to resolve during the transformation of the data.

Implementation Pattern
In this pattern, we process data in a stateless pipeline. Stage 1 focuses on extraction; Stage 2 focuses on structural integrity.
import json

def process_pipeline(raw_text):
    # Stage 1: Focus entirely on information density and content extraction
    summary_step = client.chat.completions.create(
        model="gpt-4o",
        messages=[
            {"role": "system", "content": "You are a specialized content extractor."},
            {"role": "user", "content": f"Extract the key entities and arguments from: {raw_text}"}
        ]
    )

    # Stage 2: Focus entirely on structural mapping
    # By providing only the summary as context, we prevent the model
    # from being distracted by the raw source material.
    json_step = client.chat.completions.create(
        model="gpt-4o",
        messages=[
            {"role": "system", "content": "You are a rigid data formatter. Output only JSON."},
            {"role": "user", "content": f"Format this extracted data into valid JSON: {summary_step.choices[0].message.content}"}
        ],
        response_format={"type": "json_object"}
    )

    return json.loads(json_step.choices[0].message.content)
Why Rejected Approaches Fail
Engineers often attempt to fix overloaded prompts using "few-shot prompting" or "system instruction weighting" within the same monolithic prompt. These methods often fail for two reasons:
- Instruction Saturation: As you add examples or nuances to a single prompt, the relative semantic weight of any single directive decreases. The model struggles to differentiate between the core task and the auxiliary formatting instructions.
- Instruction Dilution: Using system messages to define "priority" is often ignored because the model treats it as just another piece of text to be processed, rather than a system-level directive.
Serial staging is superior because it creates a clean separation of concerns. By initiating a new API call, you ensure the model receives a context window populated only by the specific data and the immediate instruction required for that step, preventing historical constraints from influencing current execution.
Intermediate Validation: The "Circuit Breaker"
Decomposition allows you to implement a validation layer between stages. This is a critical edge case handler: if Stage 1 produces an output that does not meet your minimum semantic requirement (e.g., it is too short or lacks specific entities), you can abort the pipeline before invoking the expensive and complex formatting stage.

This approach transforms your prompt engineering from a "black box" request into a testable software engineering pipeline. By asserting the validity of the input at each stage, you can log exactly where a request failed—was it the extraction (Stage 1) or the formatting (Stage 2)? This provides the observability that is entirely absent in a single-pass prompt.
When designing these pipelines, prioritize moving the most volatile tasks (like creative rewriting) to the start and the most rigid tasks (like JSON formatting or regex-style cleanup) to the terminal step. This ensures that the final step is operating on a sanitized, uniform input, which is the most reliable way to maintain deterministic output at scale.
Want the prompt this article describes, built for your own objective?
Engineer one now — free, no account needed