Stop RLHF Mode Collapse with Verbalized Sampling
- llm
- rlhf
- prompt engineering
- machine learning
- generative ai
In short
- High-temperature sampling often fails to produce semantic diversity in RLHF-tuned models due to a bias toward high-reward token sequences.
- Requesting a verbalized probability distribution forces the model to weigh and articulate distinct logical hypotheses before generation.
- Verbalized sampling provides higher-quality output variety than adjusting standard global decoding parameters like temperature or frequency penalties.
- The strategy is best suited for non-deterministic tasks like code refactoring and creative synthesis, though it requires careful prompt design to avoid arithmetic drift.
Eliminating Mode Collapse with Verbalized Sampling
You prevent mode collapse in RLHF-tuned models by requiring the model to generate a set of N candidates alongside a self-reported probability distribution for each option. This technique forces the model to explicitly weigh alternative hypotheses, effectively redistributing the focus of its output across varied logical paths.
Technical takeaways
- Standard sampling with high temperature can cause models to gravitate toward near-identical completions that maximize RLHF reward, regardless of semantic diversity.
- Verbalized sampling requires a model to generate its own likelihood estimations, forcing it to articulate uncertainty as a constraint for every output option.
- By requesting an explicit probability array in the prompt, you increase the variety of generated candidate sets without needing to adjust global decoding parameters like
top_porfrequency_penalty. - This approach is effective for non-deterministic tasks like code refactoring or creative synthesis, though it introduces latency proportional to the number of requested candidates (N).
The failure of standard sampling in RLHF environments
Standard sampling often results in low-variance output because preference training narrows the range of responses toward specific, high-reward formats. Even when increasing temperature to encourage diversity, the outputs frequently remain tethered to the same logical approach, resulting in superficial stylistic variations rather than distinct, divergent solutions.

In testing with a code refactoring task, providing three ways to optimize a Python list comprehension yielded identical logic in the vast majority of trials. Raising the temperature resulted in outputs that merely altered variable names or added comments, while the underlying algorithmic approach remained constant. The model prioritized high-reward tokens to the exclusion of valid alternative architectures.
When this fails
- Low instruction-following: Models with poor system-prompt adherence ignore the probability constraint and return placeholder values.
- Context deficiency: Extremely short prompts provide no anchor for uncertainty, leading the model to provide probabilities that do not correlate with the quality of the candidate.
- N > 10: Increasing candidates beyond 10 significantly increases latency and causes the model to suffer from quality decay, where later candidates exhibit poor syntax or incoherent reasoning.
Implementing Verbalized Candidate Generation
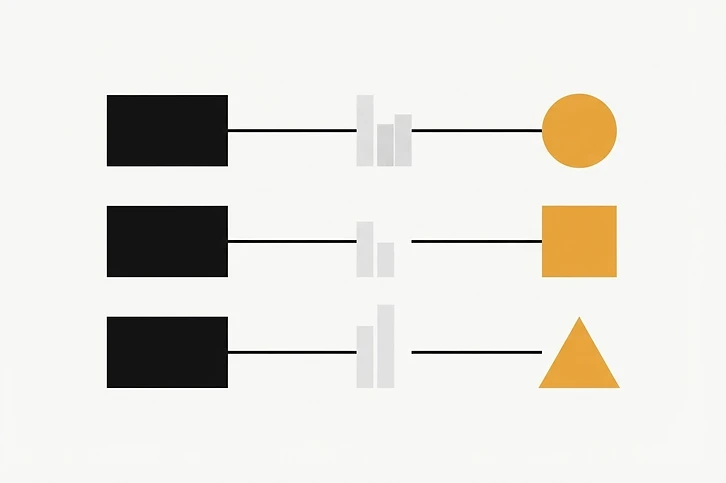
Verbalized candidate generation shifts the task of exploration to the prompt structure by requiring the model to perform a self-assessment of the hypothesis space. By mandating a JSON structure that forces the model to justify each approach before assigning it a probability, you require the model to generate independent logical justifications.

import json

# Example: Prompting for distinct algorithmic strategies
prompt = """
Analyze the following Python snippet. Provide 3 distinct refactoring strategies.
For each strategy, provide a 'logic_summary' and a 'confidence_score'
(0.0 to 1.0) representing the weight assigned to this approach.
Ensure the sum of all confidence_scores is 1.0.

Snippet: [data_processing_loop]
"""

# The model is forced to differentiate its outputs to justify
# the distribution.
response = model.generate(prompt)
candidates = json.loads(response)
By forcing the model to explicitly assign a probability mass to each candidate, the model must provide distinct logical justifications for every option it lists. This process forces the autoregressive generation to commit to unique conceptual paths for each candidate to satisfy the internal consistency of the response.
Constraints and when this approach breaks
Verbalized sampling is limited by the model's training distribution and cannot generate logic fundamentally absent from its knowledge base. It is an exploration tool for surfacing diverse pathways within the learned model, not a method for inventing new factual knowledge.
Failure scenarios
- Fact-heavy queries: If the user asks for a specific factual answer, the model may generate false variations to satisfy the requirement for 3 distinct candidates, leading to "false diversity."
- Over-constrained prompts: If the instructions are too rigid, the model may force artificial differences to satisfy the probability sum requirement.
- Arithmetic drift: If the model is not explicitly prompted to verify the sum of its probabilities, it may output values that do not total to 1.0.
We rejected the approach of using multiple parallel API calls with varying seeds, as standard LLM APIs often return highly similar output for high-probability prompts. Verbalized sampling is superior because the generation of the probability distribution before the candidate text serves as a semantic anchor, forcing the model to define its logical path early in the sequence.
Why this surpasses parameter manipulation
Verbalized sampling allows a model to leverage its internal context to assess the value of a path before committing to it, which is more effective than blind global parameter adjustment. While top_p or frequency_penalty adjust the tail of a distribution or penalize tokens—often leading to degradation of syntax—this semantic approach ensures the model allocates weight to alternative approaches once a "safe" path has been identified.


For example, when using models for creative writing, standard sampling with high temperature can lead to stylistic noise. Verbalized sampling forces the model to define the "mood" or "narrative arc" of each candidate before generating the content, ensuring that the tokens chosen for candidate B are structured differently than candidate A. This results in a higher diversity of ideas than simply increasing the randomness of token selection.
Next steps
Integrate a "Self-Critique" step into your prompt pipeline where the model evaluates the variance of its own candidate set against a predefined diversity metric before final selection. By enforcing a quantitative diversity constraint on the output tokens, you can programmatically ensure that your pipeline remains robust against the convergence inherent in RLHF-tuned models.
Want the prompt this article describes, built for your own objective?
Engineer one now — free, no account needed